Lesson 02
Getting Started with ETL and ELT
Learn ETL vs ELT for data engineering: batch vs streaming pipelines, data integration patterns, and common orchestration tools.
Getting Started with ETL and ELT
ETL vs ELT, batch vs streaming, orchestration, and how the ETL developer role became data engineering.
What is ETL?
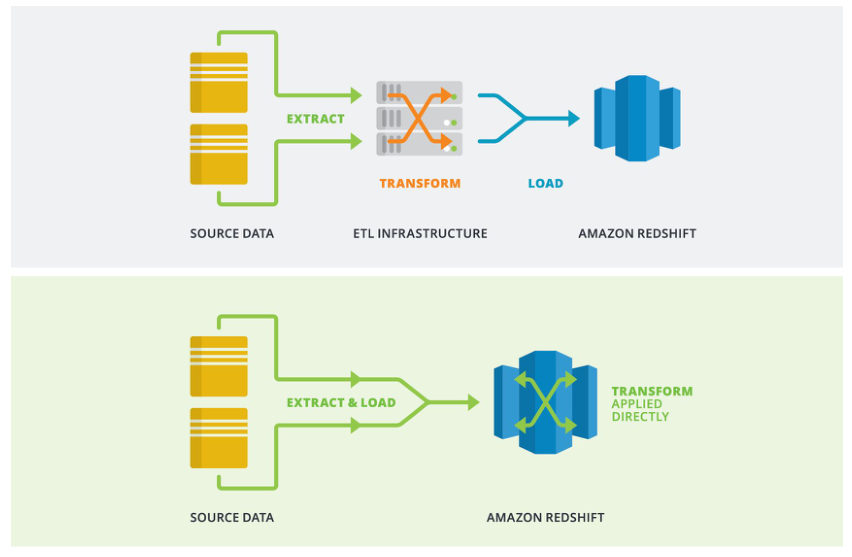
ETL (Extract, Transform, Load) connects the source systems where the business generates data with the target: a data warehouse, database, data lake or lakehouse. It is an integral part of designing and building a data warehouse.
Wikipedia’s definition: ETL is a three-phase process where data is extracted from an input source, transformed (including cleaning), and loaded into an output data container.
- Data can come from one or more sources and go to one or more destinations. For a warehouse the ideal case is many sources and a single destination.
- ETL is usually run by software, but it can also be done by hand or with code.
- ETL software automates the whole process. It runs manually or on a schedule, as single jobs or grouped into batches of jobs.
- Jobs depend on each other and form a DAG (Directed Acyclic Graph). The term is common in dbt and Airflow.
ETL example
Two files, orders.csv and products.csv, must land in a database (Postgres or a cloud warehouse, it doesn’t matter).
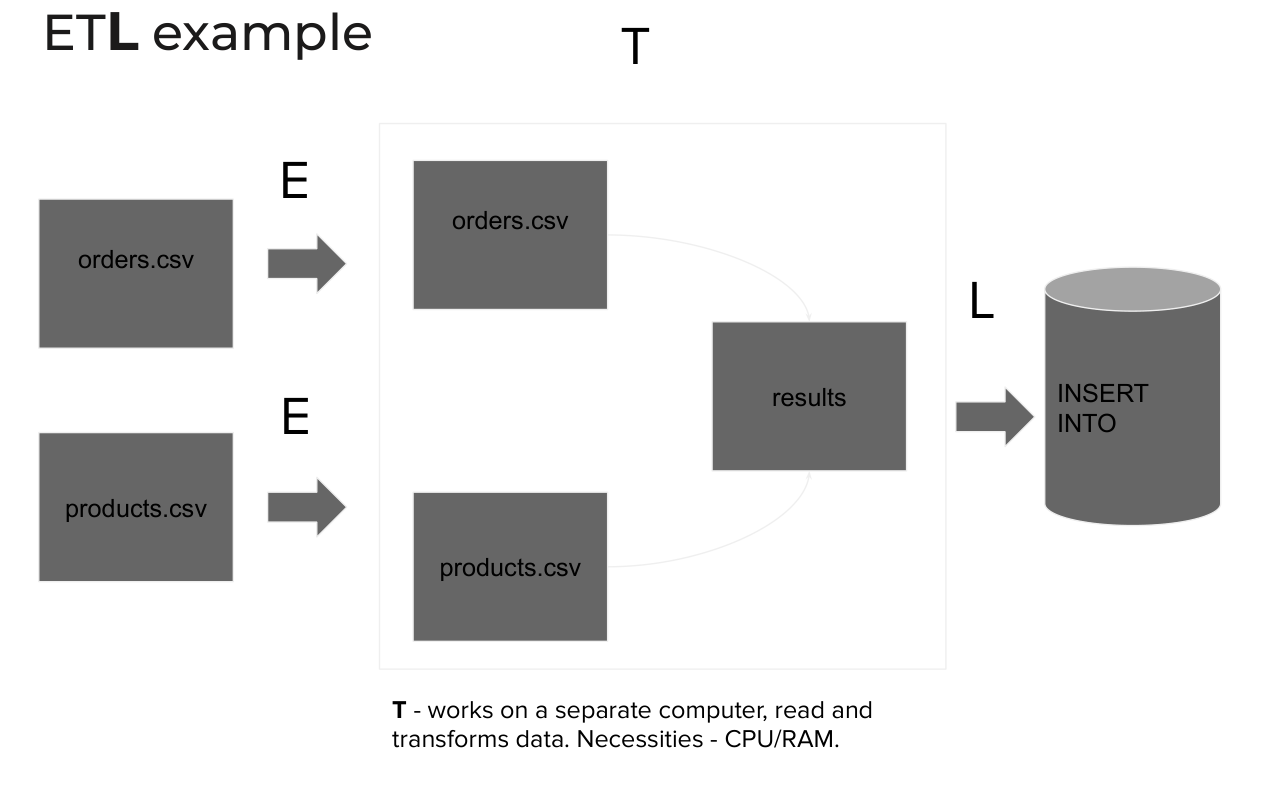
- Extract: a tool (or just a Python script) opens the files and reads them row by row.
- Transform: cleaning, joins and other changes happen inside the tool, on its own machine.
- Load: the finished result is written to the target table with
INSERT INTO.
The key point: the transformation runs outside the warehouse, so you need separate compute for it (CPU, RAM): a container or a server that hosts the tool or script.
ELT example
The same two files, but the order of steps changes.
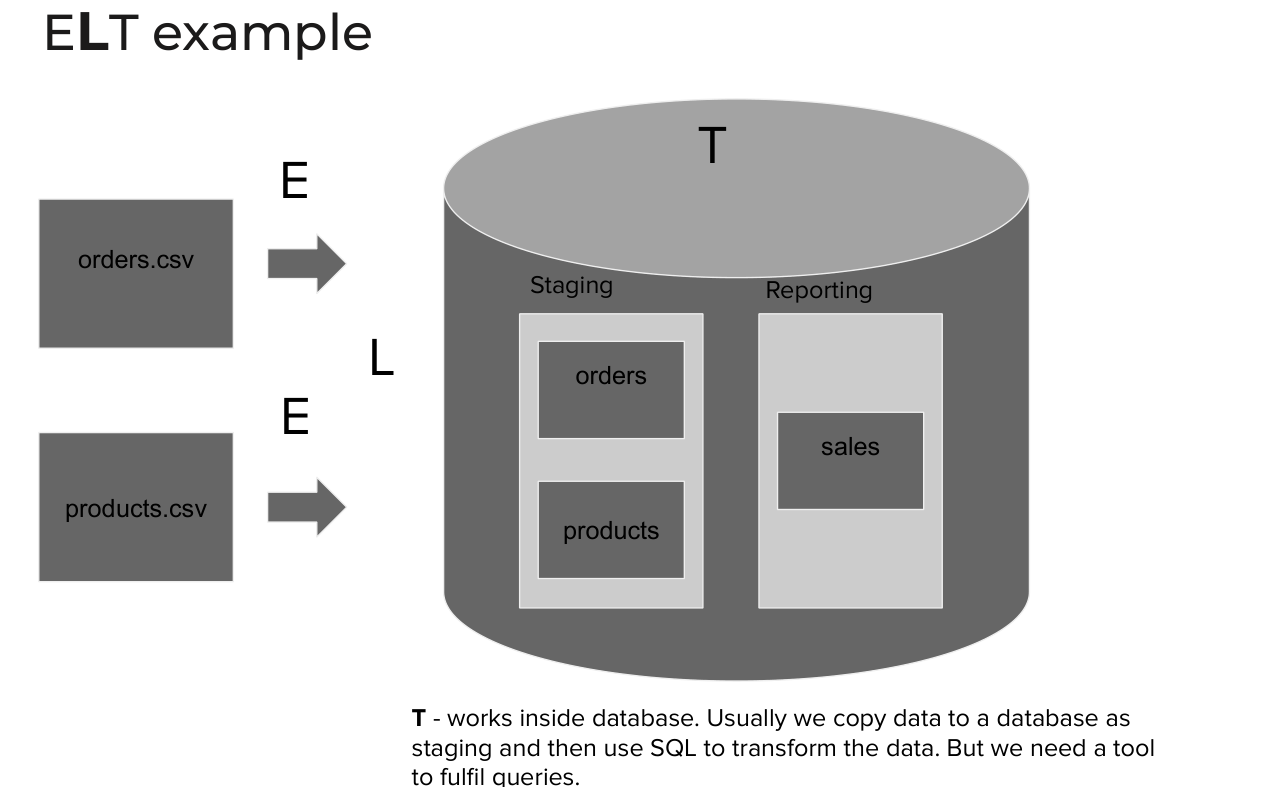
- Extract: take the files as they are. You don’t need to read every line, only to know the schema.
- Load: push them into staging (landing) tables that mirror the files:
ordersandproducts. - Transform: inside the warehouse, with SQL, merge and clean them into a
salesfact table in the reporting area.
No intermediate application or server. The idea is that a cloud or analytical warehouse is powerful enough to read the files and process them itself. You still need a tool to run the queries.
ETL vs ELT
| ETL | ELT | |
|---|---|---|
| Order | Extract → Transform → Load | Extract → Load → Transform |
| Extract | Connect to a source (file, database via JDBC/ODBC, API, FTP) | Same |
| Transform | In a separate tool or script: filter, aggregate, join, create fields, control data quality, model the data | In the warehouse, with SQL or Python (under the hood it is SQL anyway) |
| Load | INSERT INTO vs bulk load | Same |
| Needs | Separate compute, usually an ETL tool with a GUI | A powerful warehouse |
| Last step | Load | Transform |
“What is the difference between ETL and ELT?” is a very common interview question. Answer with the two examples above.
Orchestration
An orchestrator is a scheduler that triggers jobs. The Linux cron is the same idea in its simplest form. Orchestration tools add a UI and more flexibility.
Airflow is the most popular open-source one:
- As a pure orchestrator it only triggers the work: load the file into the warehouse, then run a script, dbt or SQLMesh to transform it there (ELT).
- It can also do the work itself: read files in Python, connect to a database over JDBC, transform, and write the final result to the warehouse (ETL).
So Airflow is not only a job runner, it can do both. To feel the difference, run it and build both kinds of jobs. To use Airflow you need to read Python (variables, functions, packages), not be an expert.
Another tool in the course is Pentaho Kettle: a very old tool, once open source, acquired by Hitachi. It has a visual UI, runs on Linux, macOS and Windows, can be scheduled and hosted, and does everything you need. It is a good starting exercise.
Batch vs streaming
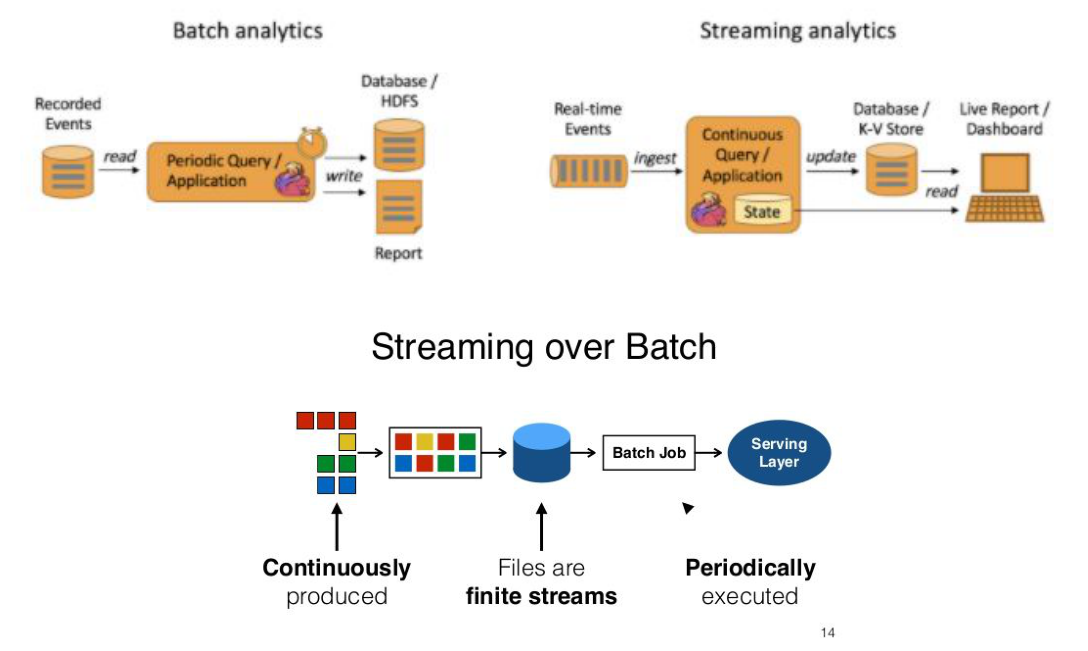
| Batch | Streaming | |
|---|---|---|
| When it runs | On a schedule: every 15–30 minutes, every hour, every night | As soon as an event is generated, 24x7 |
| Typical tools | dbt, Airflow, ETL tools | Apache Kafka, Kinesis, Azure Event Hub |
| Fits | Data warehouses; this is “true” ETL/ELT | Data lakes and lakehouses; works less well with warehouses (Snowflake dynamic tables help, but not a lot) |
- Micro-batch is a batch every 5–15 minutes.
- Most warehouses refresh overnight. Better systems run every hour and add only new data.
- Full reload overwrites everything on each run: expensive but simple and safe. Incremental loads only fresh data: more complicated. It can be a plain append, delete and insert, or merge (upsert).
- Streaming example: every login in a mobile app creates an event that must be sent to the server right away, for example to a Kafka topic and then to S3. A platform team or software engineers usually own this. Often you just pick those events up in a batch every hour.
In this module we focus on batch. Streaming is an advanced topic for later.
Scope of Module 4
- ETL/ELT here means data warehouses (a warehouse is sometimes called an Enterprise Data Warehouse or a data platform) and batch / micro-batch processing.
- We start on-premise: localhost Postgres, a no-code ETL tool (Pentaho), and the dimensional modeling you need: slowly changing dimensions, facts and dimensions, a path from a transaction table to a star schema for BI.
- Cloud (AWS, Azure, GCP) comes in Module 5, cloud warehouses (Snowflake, BigQuery, Synapse, Redshift) in Module 6, Spark in Module 7, big data in Module 8.
- Git from Module 0 matters now: we will use CI/CD and Docker, for example running dbt in containers with AWS Batch or GitHub Actions.
Terminology
| Term | Meaning |
|---|---|
| Job | The whole pipeline with all its transformations. Example: read Salesforce accounts, clean them, write to Snowflake every hour |
| Trigger | What starts a job: a schedule (every day at 9:00), the end of another job, or an event |
| Event | Something that happened: a login, a click. Events are append-only, history never changes |
| Schedule | Time-based trigger |
| Condition | A branch in the pipeline that depends on the data or a previous step |
| Mapping | Which source column goes to which target column |
| Lineage | The end-to-end path from a dashboard to its fact table to its sources. Mapping is lineage at column level |
| Source | CSV, OLTP database, SFTP, API, an application, or a data share (for example Snowflake to Snowflake) |
| Target | Data warehouse, data lake or lakehouse (here: Postgres DW) |
Sources split into two kinds: OLTP systems (back end of an e-commerce site, orders, transactions) and event or telemetry sources (Google Analytics, logs, JSON files), where you only ever append.
Client-server tools (on-premise)
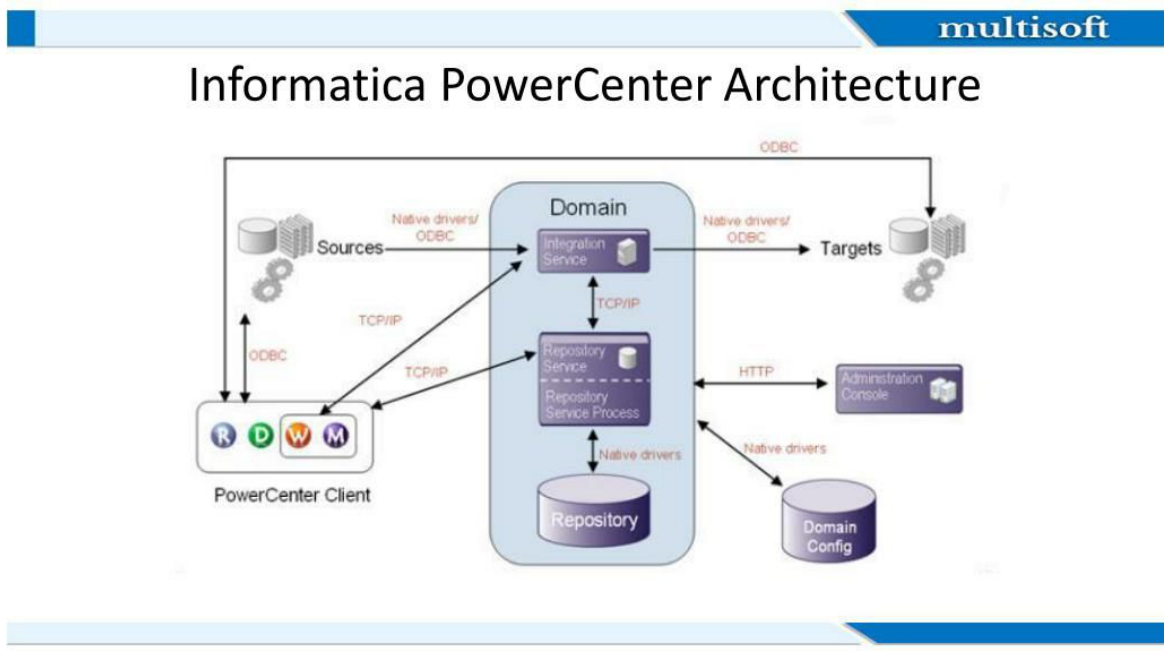
Old ETL tools work like Tableau Desktop and Tableau Server: you build on a client and publish to a server. Informatica PowerCenter is the classic example, and it was one of the biggest tools on the market. Modern tools can be browser-only, or let you write code locally and run it in the cloud.
FAQ
ETL and big data
“Big data” is not about volume anymore: a laptop can have 1–2 TB of SSD and a cloud VM over 1 TB of RAM, which is why DuckDB claims you don’t need a distributed system. In this course big data means the Apache ecosystem: Hadoop (MapReduce plus HDFS), Hive, Spark, and similar tools like Impala or Trino. ETL in big data is a transformation in Spark with PySpark or Scala: read a file, join, filter, write a new file. This is covered in Modules 7–8.
What is a data pipeline?
A sequential set of steps where the output of one step is the input of the next. The idea comes from the Unix | (pipe): Input → Pipe → Filter → Pipe → Filter → Output.
- ETL always has a transformation step. A pipeline can just copy data from a source to a destination.
- A pipeline wrapped as a job goes on a schedule, and jobs get dependencies: downstream jobs, including BI dashboard refreshes, wait for upstream ones to succeed.
- A job can succeed and still deliver wrong data. That is why you need data quality tests and data observability, and in the cloud, cost control so you don’t burn Snowflake credits.
ETL tool or coding?
You can build ETL with low-code/no-code tools or with code (Python, Scala, Rust, Go).
- Traditional warehouses often use ETL tools from the Gartner/Forrester quadrants. Big data, data lake and data platform solutions use code or a mix.
- A homemade tool in an uncommon language becomes tech debt and a black box: the author leaves, the next person wants to rewrite it in another language. Common tools with big communities are safer, and learning them improves your chances of a job.
- You don’t need Rust to get a data engineering job. Even dbt Core is just SQL, and together with Fivetran it can cover 100% of a data team’s needs.
- We start with no-code Pentaho, then dbt (code) and Airflow (orchestration, needs Python reading skills).
ETL and cloud
AWS, Azure and GCP have native tools: Azure Data Factory, GCP Dataproc, managed Airflow, Spark, and warehouses like BigQuery and Redshift where you refresh data with stored procedures. Classic ETL (Informatica, SSIS, SAP, Oracle) doesn’t keep up here: it is too expensive and inefficient compared to ELT or Spark. We still learn the difference between ETL and ELT on the simple on-premise setup first.
ETL developer vs data engineer
| ETL developer | Data engineer |
|---|---|
| Works with data warehouses (SQL) | Works with a warehouse in the cloud (AWS, Azure, GCP), see Modules 5–6 |
| On-premise solutions | Works with a data platform (data warehouse + data lake) |
| Uses a GUI, vendors like Informatica and Microsoft SSIS | May use a GUI (Matillion) or no Python, but often uses Spark for big data |
| Works with data scientists, for example scaling an ML solution | |
| CI/CD, data infrastructure, infrastructure as code, data observability, cost management |
The essence is the same: integration and transformation of data. An ETL developer is the same as a data engineer, but the data engineer has more requirements. Everyone should now know the cloud, like everyone once had to know Microsoft Office.
Next lesson
The ETL tools market: what is out there and which tools are available.
This lesson is for members only
Join Surfalytics to unlock all 2 lessons in this module, plus every module, project, mock interview, and the private community.
7-day free trial · Cancel any time
What's inside this module: